tiny-attention
Live visualizer
A FlashAttention engine in SystemVerilog, checked bit-for-bit against a golden model. It computes attention one block at a time, without storing the whole score matrix.
Explore the idea.
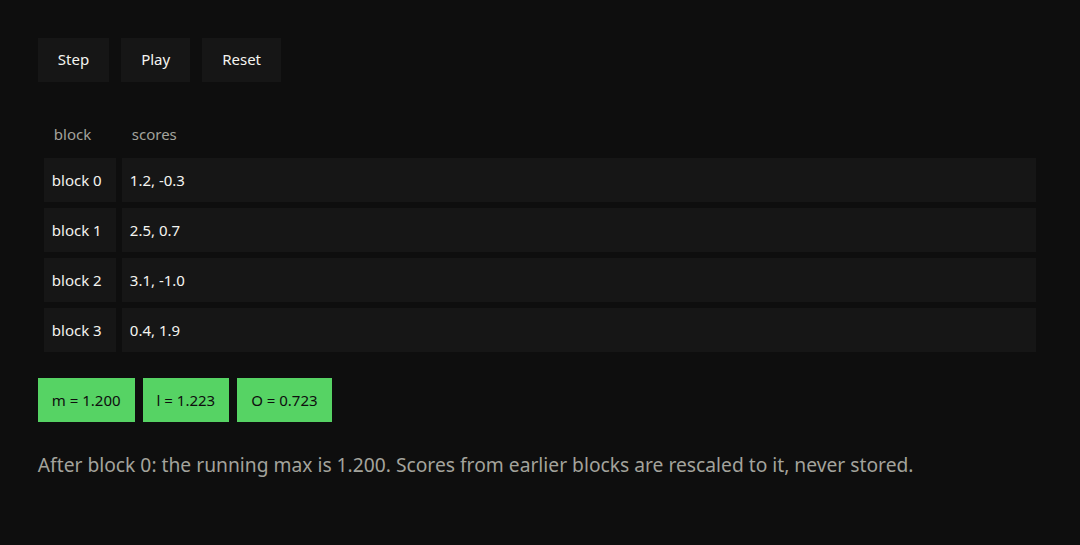
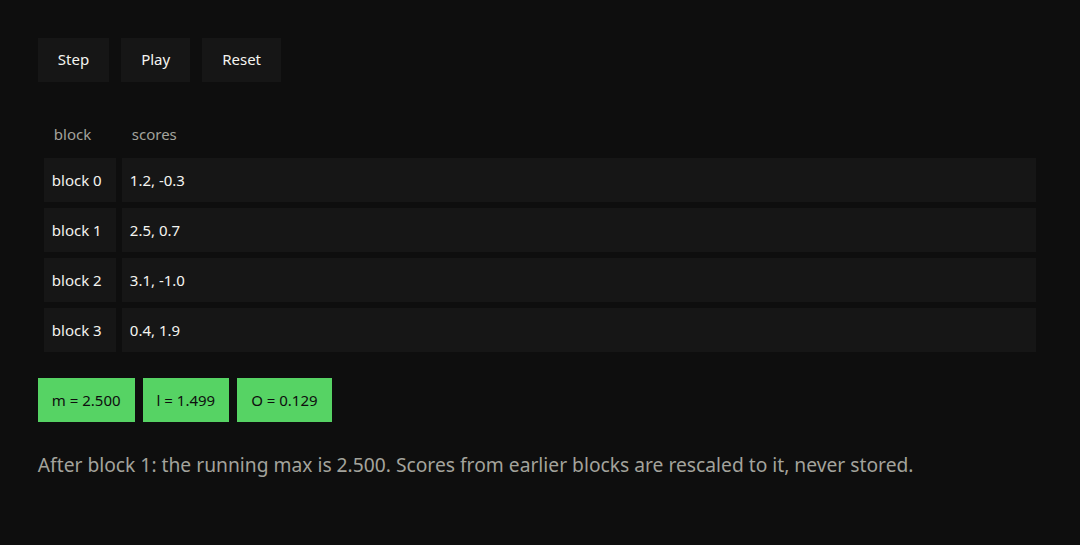
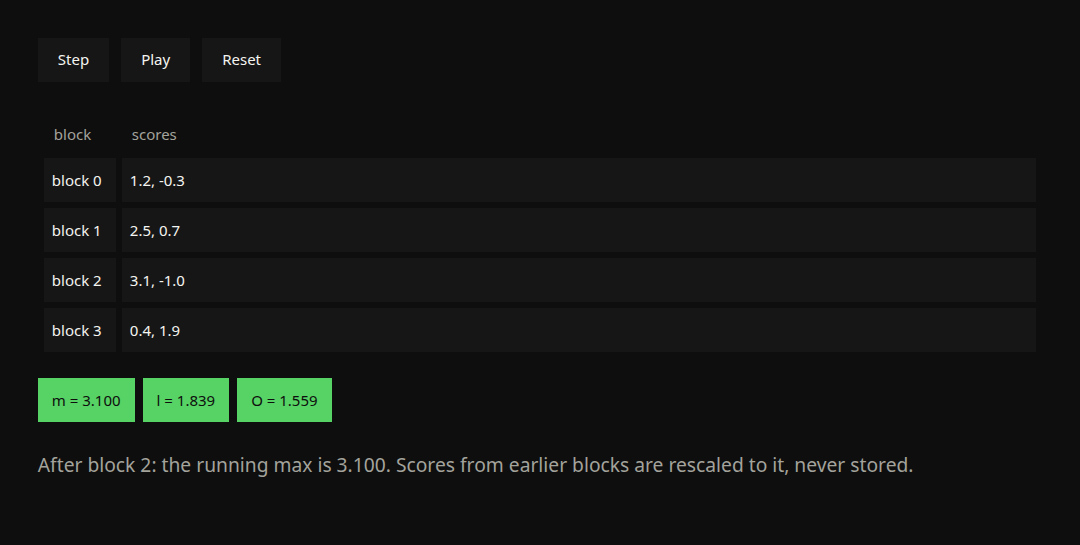
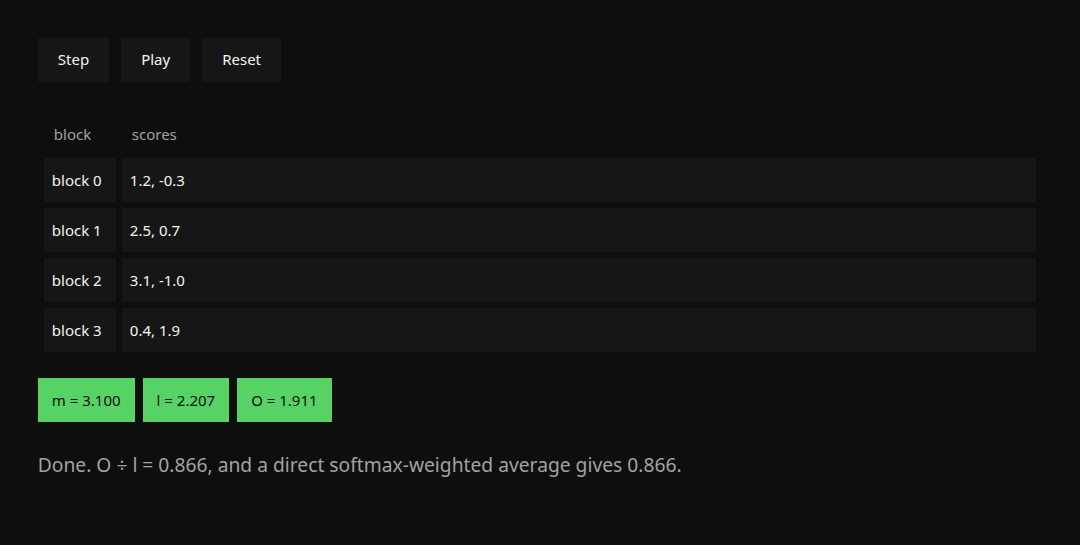
Online softmax over eight scores, in blocks of two. Each block updates the running max, sum and output. At the end, O ÷ l gives the exact softmax-weighted answer, the same as the direct formula.
Interactive illustration · Simplified model
What it shows.
Standard attention writes a full score matrix to memory. FlashAttention keeps only a few running numbers per row, so less data moves.
The live visualizer runs the compiled RTL and compares it with a golden model.
One block at a time.
Frames from the sketch as each block of scores arrives. The running max, sum and output update at every step.